preprint · 2025 · Under internal review · no results disclosed
Towards Foundational Models in Mammography: Leveraging Vision-Language Models for Radiological Reasoning
Not peer reviewed.
What this paper does
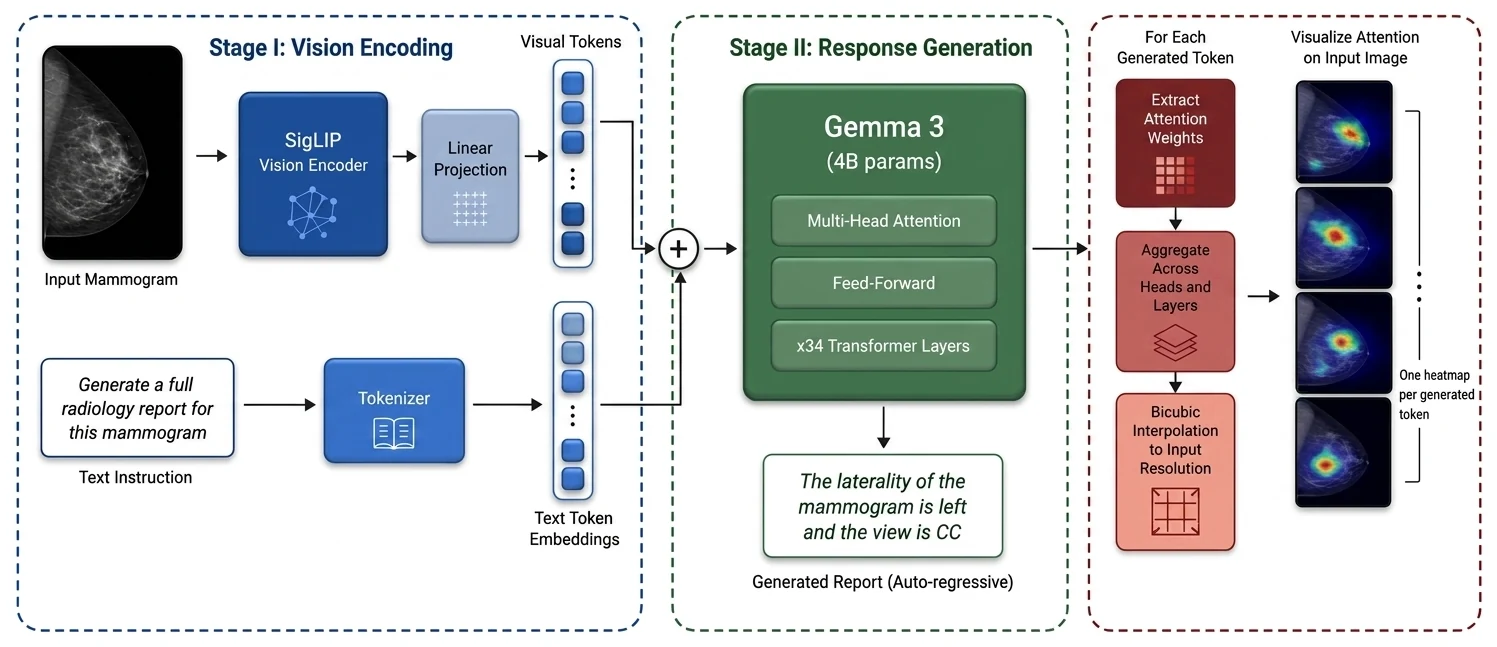
A journal manuscript on vision-language foundation models for mammography, focused on whether image-text representation learning can support structured radiological reasoning rather than a single classification output. It is listed here for completeness of the record: the work is under internal review, no venue has been assigned, and no quantitative results are publicly available, so this page deliberately contains no numbers. The related and more developed strand of this line of work — token-level attention grounding of generated mammography reports — is written up separately on this site.
How
Vision-language representation learning connecting mammography images with radiology language and reasoning-oriented model outputs. Methodological detail is withheld while the manuscript is under review.
Reported results
- Under internal review. No quantitative results are publicly disclosed and none are reproduced here.
Relevance
Reasoning-oriented foundation models could make mammography AI more structured and auditable than a single-score classifier, which is the direction the rest of this work also points in.
What it does not show
Not peer reviewed, no venue, and no public results. Listed for completeness only.
Citation
A. Bhandary Panambur, S. Bhat, T.-T. Nguyen, S. Bayer, A. Maier. Towards Foundational Models in Mammography: Leveraging Vision-Language Models for Radiological Reasoning. Journal submission, under internal review, 2025.
View original abstract
A journal submission on vision-language foundation models for mammography, focused on image-text representation learning and structured radiological reasoning rather than single-task image classification. The manuscript is under internal review and no quantitative results are publicly available.